Forms rather than prompts: what a System One model contributes to chat assistants and generated dashboards
In an Agentic UI, a model sits between the user and the application. Each message triggers at least one model call, and that call has to choose a tool, populate its arguments, and settle on a widget to render. When an LLM handles this step, the wait is often measured in seconds and every invocation adds cost. For an interface, neither is acceptable.
Jev goes another way. Its vendor TypeSafe describes it as the first model of a class they call System One. Rather than producing text, such a model answers predefined questions by picking from predefined options, and it does so in roughly 100 milliseconds. I received an early preview and want to summarize below what Jev can offer Agentic UI.
Two branches live in the repository. The first, main, puts Angular, CopilotKit, AG-UI, and Jev together. The second, console-chat, keeps Jev on the console alone and serves as a quick overview.
What Jev Actually Is
Text generation happens token by token when an LLM receives a prompt. Whenever the application needs a decision out of that, it must request structured output, then parse and validate whatever comes back. Jev removes those steps entirely. You give it a state — the conversation history, for example — along with a collection of typed questions. For every question it hands back one of the answers you defined, plus a probability attached to each option.
Picture a questionnaire and you have the right mental model. A form is passed to the model together with the text it has to judge, and the model ticks exactly one box per question. There is no room to write in the margins. Your own code then reads those ticked boxes and decides the next move: invoke a tool, render a widget, or ask the user something further.
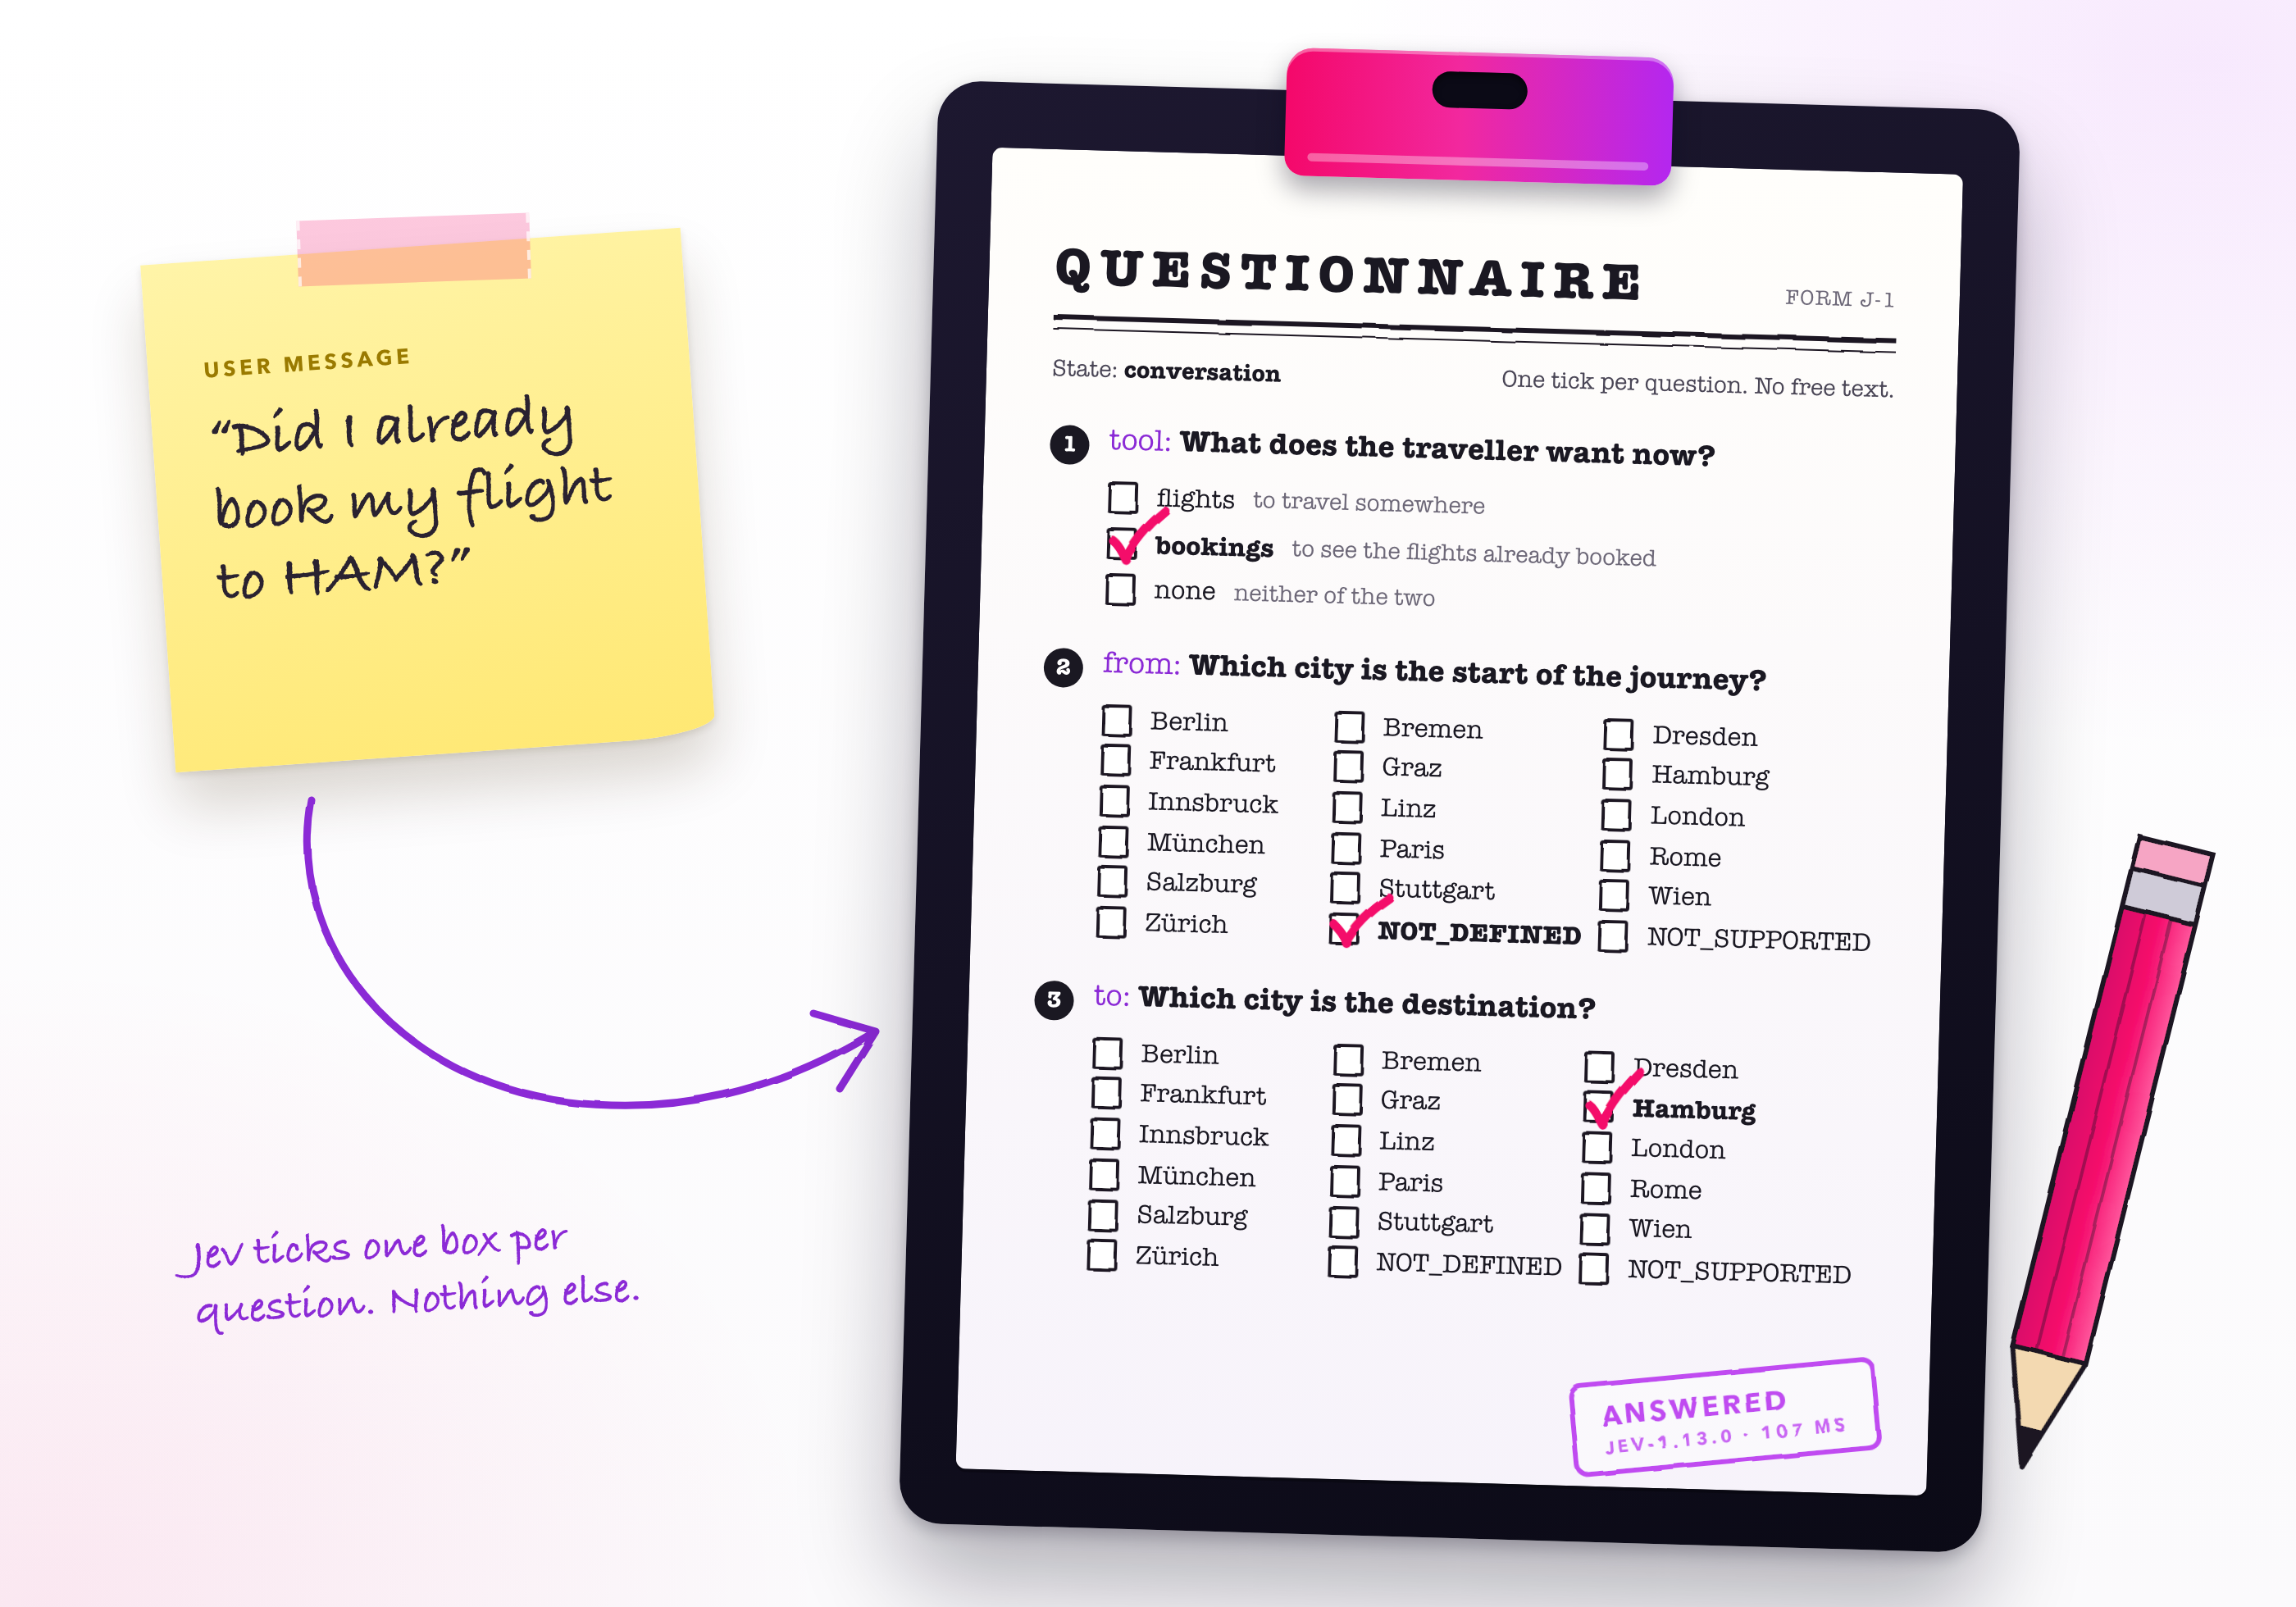
Two consequences follow from this setup. Answers arrive typed, so what reaches your code always matches a value your code anticipates. And within one request, every question is resolved independently and in parallel. TypeSafe states that extending the questionnaire has hardly any impact on response time.
The Example Application
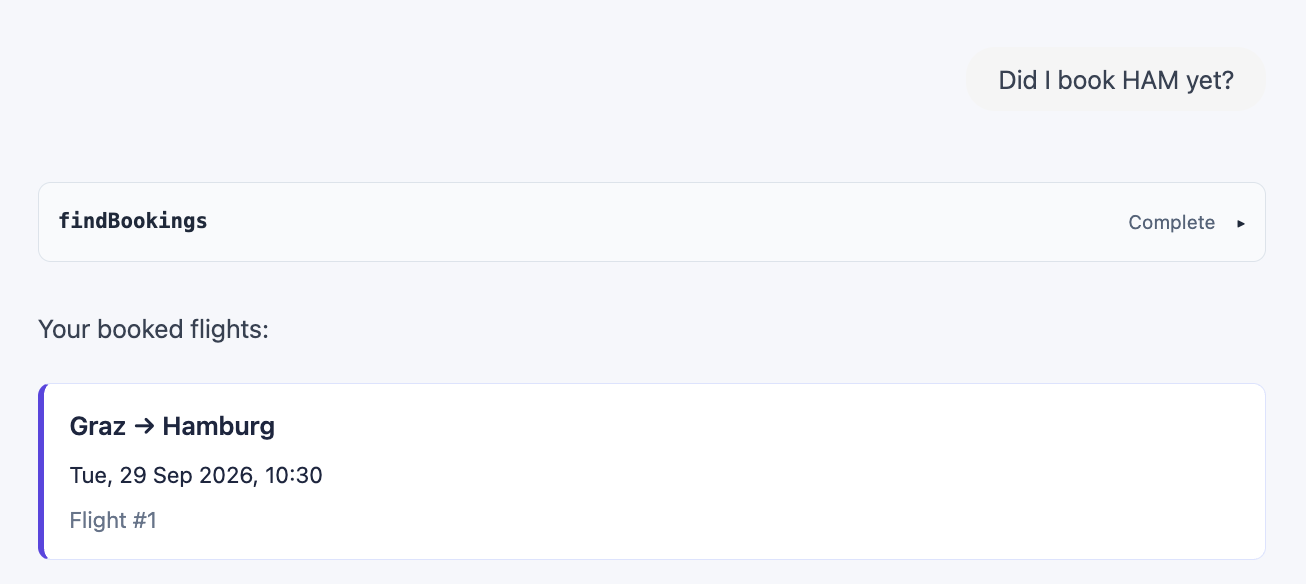
What I built is a compact flight assistant with two views. From the chat, users request flights or look up their bookings. Jev picks the tool and supplies its arguments, the server executes the tool, and the result streams back through AG-UI. CopilotKit renders each flight as a widget on the client:
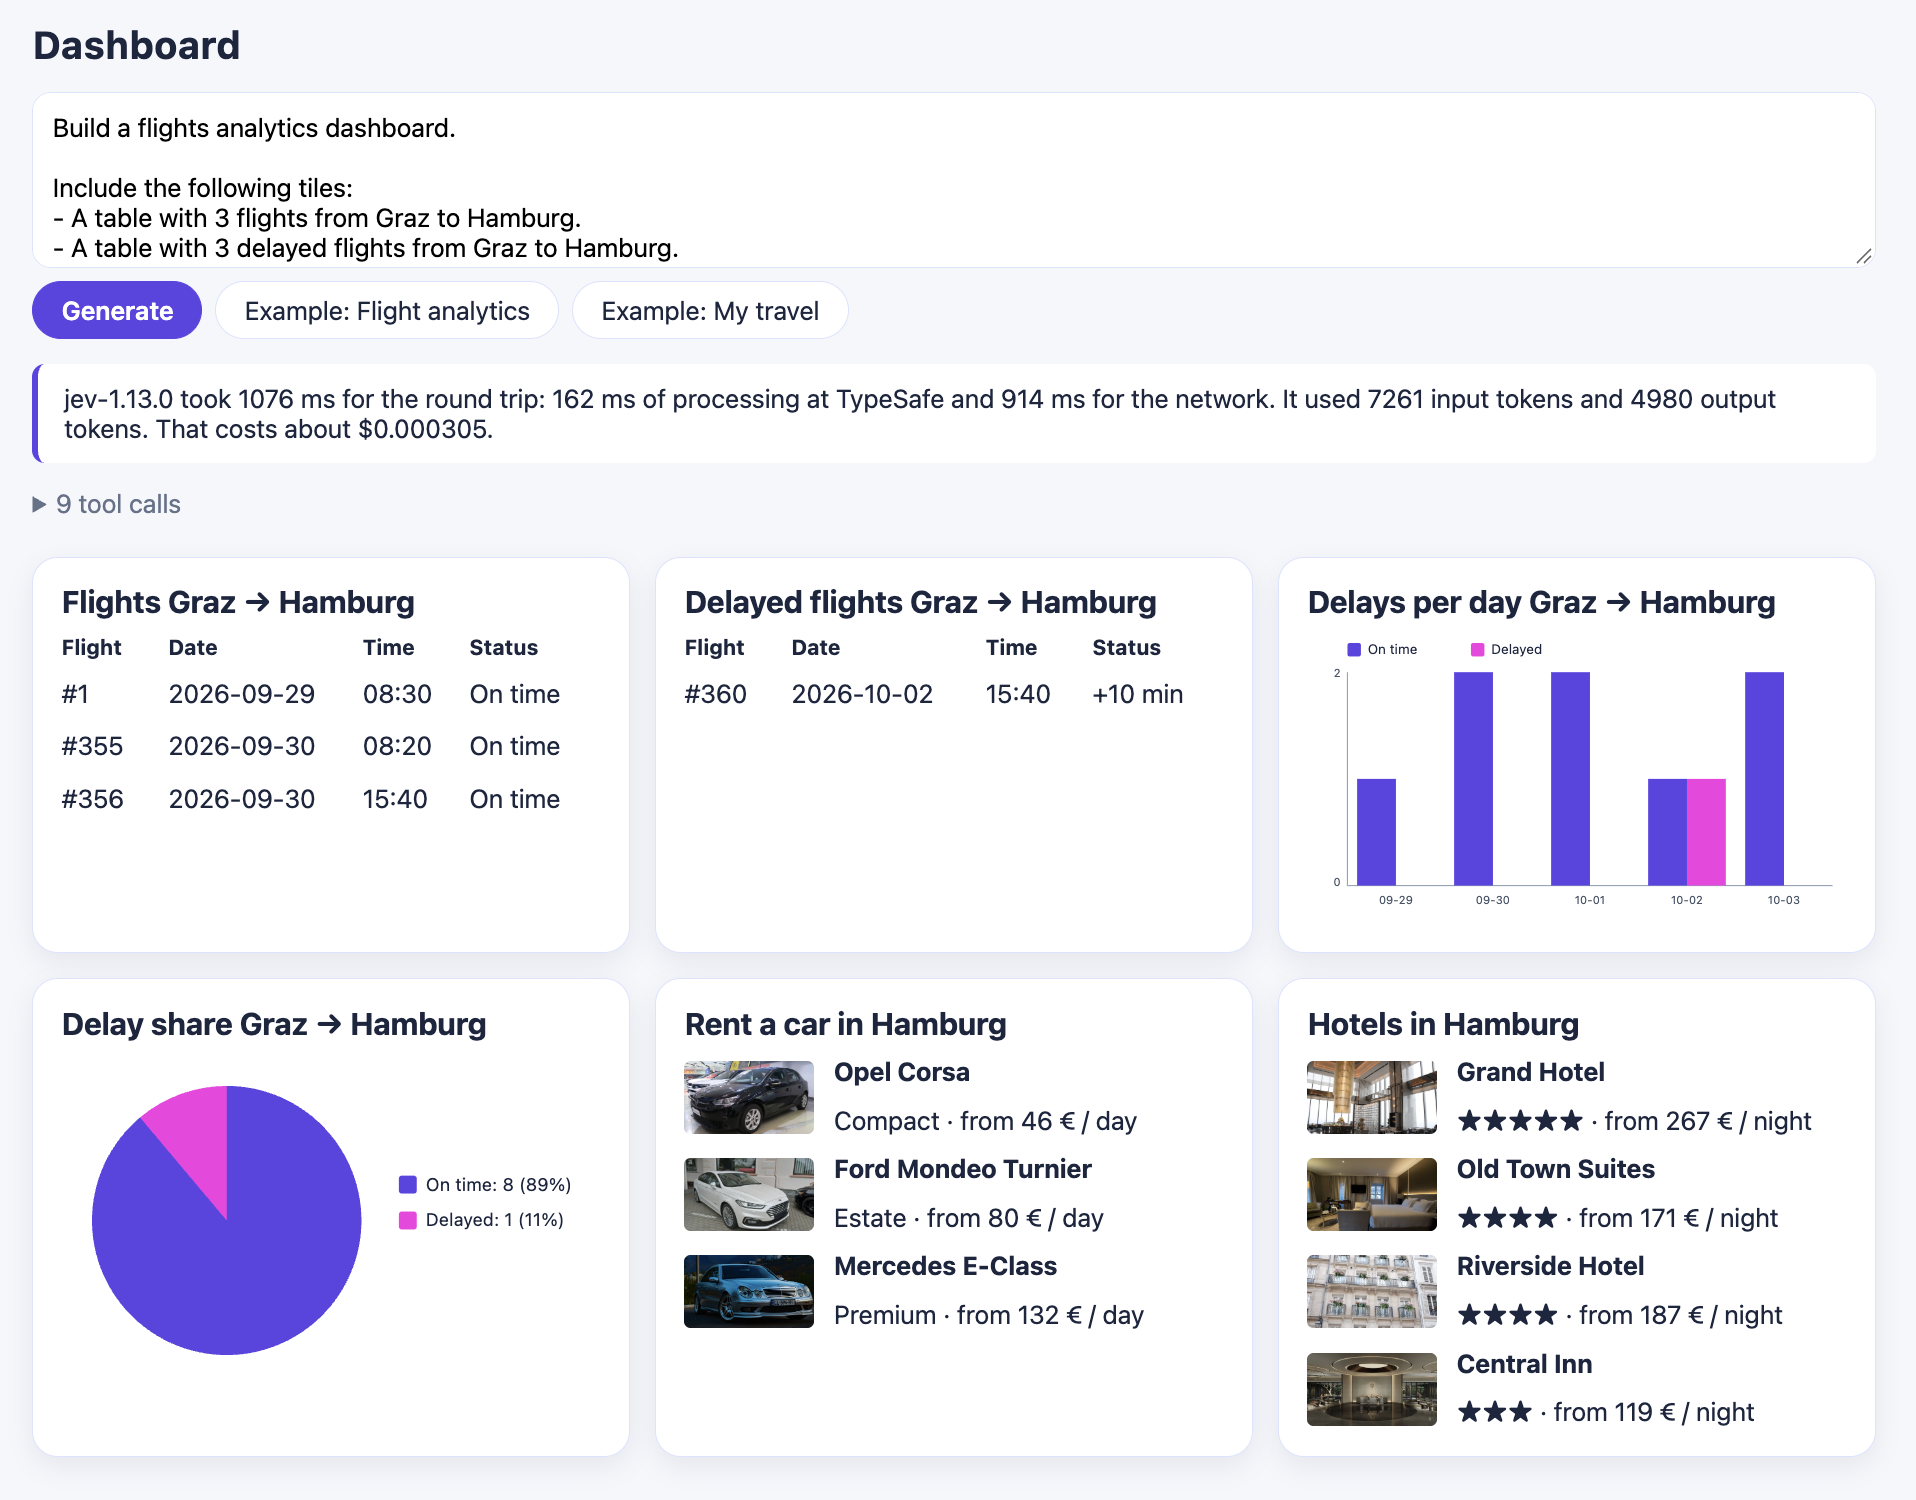
The dashboard goes further. A user describes which tiles should appear, and Jev answers a bigger questionnaire about that description: which tiles are wanted, for which route, how many entries, in what order. The server then invokes the necessary tools and ships the dashboard to the client as A2UI:
Getting Started
npm is how the SDK is distributed:
npm install @typesafe-ai/sdkTypeSafe also ships a skill that familiarizes coding agents with the question types, the patterns, and the best practices. Installing it for Claude Code happens as a plugin, while for other agents the skills CLI handles it:
# Claude Code
claude plugin marketplace add typesafe-ai/skills
claude plugin install typesafe@typesafe-ai

# Other agents
npx skills add typesafe-ai/skills --skill typesafe-ai
Defining the Questionnaire
Three questions make up the questionnaire for our chat — one to select the tool, two more to determine its arguments:
import { choice } from '@typesafe-ai/sdk';

[...]

const CITIES = {
  'Berlin': null, 'Bremen': null, 'Dresden': null, 'Frankfurt': null,
  'Graz': null, 'Hamburg': null, 'Innsbruck': null, 'Linz': null,
  'London': null, 'München': null, 'Paris': null, 'Rome': null,
  'Salzburg': null, 'Stuttgart': null, 'Wien': null, 'Zürich': null,
} as const;

const CITY_OPTIONS = {
  ...CITIES,
  'NOT_DEFINED': 'No place is named for this end of the journey.',
  'NOT_SUPPORTED': 'A place is named, but it is not one of the cities listed here.',
} as const;

const CITY_NAMES = Object.keys(CITIES);

const QUESTIONS = {
  tool: choice(
    'A traveller writes to an assistant that searches flights and lists the flights ' +
      'they have booked. `conversation` is the exchange so far; the last entry is the ' +
      'new message. What do they want now?',
    {
      flights: 'To travel somewhere, or to see connections between two places.',
      bookings: 'To see the flights they have already booked: their own reservations.',
      none:
        'Neither: a greeting, a thank-you, or something this assistant cannot do, ' +
        'such as hotels or trains.',
    },
  ),

  from: choice(
    'Which city does the traveller now name as the start of the journey, the place departed ' +
      'from? The last entry of `conversation` is the new message; earlier entries count only ' +
      'when the new message builds on them, as a return flight does.',
    CITY_OPTIONS,
  ),

  to: choice(
    'Which city does the traveller now name as the end of the journey, the destination? ' +
      'The last entry of `conversation` is the new message; earlier entries count only when ' +
      'the new message builds on them, as a return flight does.',
    CITY_OPTIONS,
  ),
};
Every question here is a choice. It receives the question text, plus an object describing the possible answers: the keys are the options and the values are their descriptions. Where a key is self-explanatory, as with the city names, null suffices. The word conversation appearing in the question texts refers to the property of the same name on the state that we hand over afterwards.
Because the possible answers have to be fixed in advance, the two city questions each need two extra options. Messages that mention no city at all are covered by NOT_DEFINED. Cities the airline doesn't fly to are covered by NOT_SUPPORTED. Skip those options and the model would be forced to tick one of the 16 cities even for a message that names none.
A question currently accepts at most 255 options. Anything larger requires some inventiveness; I return to that point near the end.
Further Question Types
Two more question types exist alongside choice:
noulposes a yes/no question and reports the probability that the answer is yes.scorerates the state on ordered levels that you define yourself — the urgency of a request ranging from "can wait" to "act now," for instance. A result can also fall between two levels.
For the dashboard, one noul per tile type determines which tiles the description is asking for:
import { noul } from '@typesafe-ai/sdk';

[...]

const QUESTIONS = {
  hotels: noul(`Do they ask for hotels?`),
  [...]
};
Asking Jev
The state and all questions travel in a single call:
import { TypeSafeClient } from '@typesafe-ai/sdk';

[...]

const client = new TypeSafeClient();
const state = { conversation };
const result = await client.systemOne({ state, questions: QUESTIONS });
The API key is read from the environment variable TYPESAFE_API_KEY. Since the key must remain secret, this call has to run on the server.
Any JSON structure can serve as the state. In this case it holds only the conversation — an array containing the user's and the assistant's messages. Keeping that history lets users refer back to the flight that was just under discussion. If someone searches flights from Graz to Hamburg and then asks about the return flight, the meaning is obvious: Hamburg becomes the origin and Graz the destination. The question texts above prepare Jev for exactly this situation by stating that earlier entries matter only when the new message builds on them.
Agentic UI with Angular
If you don’t just want to connect an agent but embed Agentic UI into a scalable architecture:
In my book Agentic UI with Angular, I cover the underlying patterns and trade-offs in depth.
Reading the Result
Asked Did I already book my flight to HAM?, Jev came back with the following:
{
  "model": "jev-1.13.0",
  "answers": {
    "tool": {
      "type": "choice",
      "choice": "bookings",
      "confidence": 0.99,
      "probabilities": {
        "flights": 0,
        "none": 0,
        "bookings": 1
      }
    },
    "from": {
      "type": "choice",
      "choice": "NOT_DEFINED",
      "confidence": 0.92,
      "probabilities": {
        "Paris": 0,
        "Salzburg": 0,
        [...]
        "NOT_DEFINED": 0.93,
        [...]
      }
    },
    "to": {
      "type": "choice",
      "choice": "Hamburg",
      "confidence": 0.99,
      "probabilities": {
        [...]
        "Hamburg": 1,
        "NOT_SUPPORTED": 0,
        [...]
      }
    }
  },
  "usage": {
    "input_tokens": 891,
    "output_tokens": 365
  }
}
One entry per question appears in the answers object, mirroring the questionnaire. Three pieces of information sit inside each entry:
choiceis the selected option.probabilitiesholds a value for every option.confidenceis a number between 0 and 1 that summarizes how clearly one option stands out from the others.
Here, Jev selects the tool bookings and maps the airport code HAM to Hamburg. No departure city is named in the message, so from comes back as NOT_DEFINED. The code uses these answers to invoke the bookings tool and filter for flights to Hamburg.
Control flow benefits from the confidence value. When it drops below a threshold, the application can ask the user to confirm or clarify. And thanks to as const in the questionnaire, the result is fully typed: result.answers.to.choice is a union of the city names and the two special options, not merely a string. The usage section reports how many tokens the request consumed.
Comparison
I measured duration and cost against OpenAI's Luna. To do that, I ported the application to Luna (see the openai branch), sent the requests shown in the screenshots three times to each model, and took the best run for the comparison.
Luna was chosen because it is capable enough for this use case. According to TypeSafe, Jev can even match the larger Terra.
| Chat: Luna | Chat: Jev | Dashboard: Luna | Dashboard: Jev | |
|---|---|---|---|---|
| Model | gpt-5.6-luna | jev-1.13.0 | gpt-5.6-luna | jev-1.13.0 |
| Round trip | 1,069 ms | 716 ms | 3,207 ms | 1,078 ms |
| Processing at the provider | 708 ms | 107 ms | 2,590 ms | 204 ms |
| Network | 361 ms | 609 ms | 617 ms | 874 ms |
| Input tokens | 856 | 937 | 7,494 | 7,260 |
| Output tokens | 23 | 370 | 326 | 4,982 |
| Cost per request | $0.000199 | $0.000039 | $0.000542 | $0.000305 |
Duration
Provider-side processing time is the most striking figure. Jev needs 107 ms for the chat request where Luna takes 708 ms. For the dashboard the numbers are 204 ms against 2,590 ms. That makes Jev over 6 times faster in the first case and over 12 times faster in the second.
The round trip shows a narrower gap, since Jev's total is dominated by the network. In my measurements the network portion was larger for TypeSafe than for OpenAI, though that share depends on my location and on where the endpoints are hosted — it says little about the model itself.
Repeat runs surfaced another difference. Across all six runs, Jev's processing time remained between 107 and 204 ms. Luna ranged from 708 to 1,683 ms on the chat request, and one dashboard run took nearly 13 seconds.
Cost
The calculation is based on both vendors' list prices as of September 20, 2026, the day the measurements were taken. Prices are in USD per million tokens:
| Model | Input | Cached input | Output |
|---|---|---|---|
| gpt-5.6-luna | $0.20 | $0.02 | $1.20 |
| jev-1.13.0 | $0.042 | n/a | $0.00 |
For the chat request, Jev costs roughly a fifth. On the dashboard, Jev lands at a little more than half of Luna's price — and there Luna already profits from prompt caching, since 7,491 of its 7,494 input tokens came from the cache.
Jev reports considerably more output tokens than Luna. Those never reach the bill, because TypeSafe charges for input tokens only.
Three runs per request is a spot check rather than a benchmark, but the tendency is unmistakable.
Interested in production-ready Agentic UI architectures?
In my workshop, we dive into AG-UI, A2UI, MCP Apps, HITL patterns, and modern Angular architectures for real-world agentic systems.
Assessment and Outlook
Performance and Cost
Both dimensions look very promising for Agentic UI. Processing times of 100 to 200 ms mean the model no longer dictates how responsive an application feels. I also expect the model class Jev popularized to suit local execution well — in the browser, for instance — which would eliminate the network share too.
What Remains Your Job
A simplification runs through the examples above: widget and tile selection are coupled directly to the respective tool calls. Decoupling them would be possible, but with Jev that turns into programming work. The same holds for mapping values between tool results and widgets or follow-up tool calls — that code is yours to write. An LLM, by contrast, takes on such tasks with little effort on our side.
Further Use Cases
Agentic UI is just one possible field. The documentation lists several more:
- Routing: classify incoming requests and hand each one to plain code, a specialized LLM, or a human.
- Guardrails: screen the messages going into and coming out of an LLM application.
- Reranking for RAG: judge retrieved passages before they reach the answering model.
- Verification: check citations or extracted fields against the source document.
- Classification at scale: sort tickets, documents, or product data and moderate content.
Thinking in Classes
Working with questionnaires and predefined options — which are classes in the end — takes adjustment. Certain use cases and their implementation demand a different mindset, particularly because not everything can be expressed as a class.
Jev's documentation illustrates a few approaches. Dates, for example, can be broken into their parts — year, month, day — with separate questions determining each part and code reassembling them. A hierarchical route also works: ask for the continent first, then the country, and finally the airport.
Another approach applies when the desired value is already present in the message, such as a number or a quantity. There you can pre-filter the message with a regular expression and present the values you find as options.
Outlook: Polyglot and Hybrid Approaches
A polyglot setup offers another answer for values that resist classification. It pairs Jev with a very lean language model such as Gemini Nano, which is demonstrably strong at extraction tasks. I can picture both running in the browser.
A hybrid of the two worlds is likewise an exciting prospect, with the advantage that developers wouldn't have to juggle two kinds of models and mediate between them.
So — trend or game changer? For the decisions inside an Agentic UI, I see game-changer potential. The chosen tool and its arguments arrive typed, with probabilities, after 100 to 200 ms of processing. Free-form values and generated text still call for a language model. That is why the combination of both worlds strikes me as the most interesting prospect.